Published
Two-Column Resume vs ATS: What Parsers Read in 15 Layouts
We built one resume in 15 layouts and extracted each with pdf.js, pdftotext and mammoth. Columns, letter spacing and Word headers reordered or lost text.
TL;DR: Can an ATS read a two-column resume? Sometimes, and you can't tell which systems will. We built one resume in 15 layouts and extracted each with three open-source tools. The single-column version came out identical in every extraction. Every two-column version came out reordered or with sentences cut in half by at least one tool, and letter-spaced headings turned into "E X P E R I E N C E". Use one column, plain headings, and contact details in the body.
Can an ATS read a two-column resume?
The vendors give two different answers. Textkernel, one of the large parsing companies, says its parser handles "both single and multi-column resumes" and lists column layout auto-detection as a feature. Greenhouse, the ATS vendor, publishes a support article on why a resume fails to parse, and its list of formatting causes includes "Resumes that have a columned layout", "A resume with spaces between the letters" and "Resumes with the name and contact information in the header, footer, or text box". When a parse fails there, the file is only attached to your profile and someone has to type your details in by hand.
Workday's administrator guide is vaguer but points the same way: resume parsing results "can vary based on resume format and order of words", and the guide recommends resumes without images or image-based styles.
So the honest answer depends on the system the employer bought, and you rarely know that when you apply. That uncertainty is why we tested what happens to the text itself.
Text extraction: the step where software pulls characters out of a PDF or Word file, in some order, before any parser decides which words are your name, your job titles or your skills. If the order is wrong here, everything downstream inherits the error.
Parsing is a separate step from the keyword search a recruiter runs later. Our guide to ATS-friendly resume formats covers that split; this post stays on extraction.
How we tested: one resume, 15 layouts, four extractors
On 13 October 2026 we wrote a fictional resume for a product data analyst (summary, two jobs with three bullets, one degree, skills, a language) and rendered it in 11 PDF layouts with @react-pdf/renderer 4.5.1 and in 4 Word layouts with the docx 9.6.1 library. Every layout carried identical words. Only the arrangement changed.
Each PDF went through three extraction modes:
- pdf.js, Mozilla's "general-purpose, web standards-based platform for parsing and rendering PDFs", called through pdf-parse 2.4.5 (pdfjs-dist 5.4.296). It returns text roughly in the order the file wrote it.
- pdftotext from poppler 24.02 in its default mode, which the manual describes as undoing physical layout such as columns and outputting text in reading order.
- pdftotext -layout, which keeps "the original physical layout of the text" instead.
Each Word file went through mammoth 1.12.0, an open-source .docx converter.
For every run we recorded four things: whether the name, email and phone survived as written; whether the headings Summary, Experience, Education and Skills each came out as a line of their own; whether the summary and the three bullets came out as unbroken sentences; and the order in which the main sections appeared.
Results: what each layout looked like after extraction
| Layout | pdf.js | pdftotext (default) | pdftotext -layout |
|---|---|---|---|
| Single column | Clean, correct order | Clean, correct order | Clean, correct order |
| Letter spacing 0.4pt and 1pt on 11pt headings | Clean | Clean | Clean |
| Letter spacing 1.5pt and 2pt | All 4 headings split into letters | Education still split | Education still split |
| Sidebar left (contact, skills) | Contact and skills before the summary | 2 of 4 sentences cut by sidebar text | 5 side-by-side lines, 2 of 4 sentences cut |
| Sidebar right, main column written first | Contact and skills after education | Columns alternate line by line, 1 sentence cut | 4 side-by-side lines, 2 of 4 sentences cut |
| Name and contact in a floating box | Name and email come out last | Clean | Clean |
| Icon font before email, phone, location | 3 unreadable characters, details intact | Same | Same |
| Word layout (mammoth) | Result |
|---|---|
| Single column of paragraphs | Clean, correct order |
| Two columns built from a table | Text intact, sidebar cell read first |
| Name and contact in the page header | Name, email and phone missing from the output |
| Name and contact in a text box | Clean |
Two things stand out. The single column was the only arrangement that came out the same in all four tools. And the two-column files failed differently in each tool: the same file came out merely reordered in one and cut mid-sentence in another, which matches the vendors' split answer.
Why two columns break: the file's writing order wins
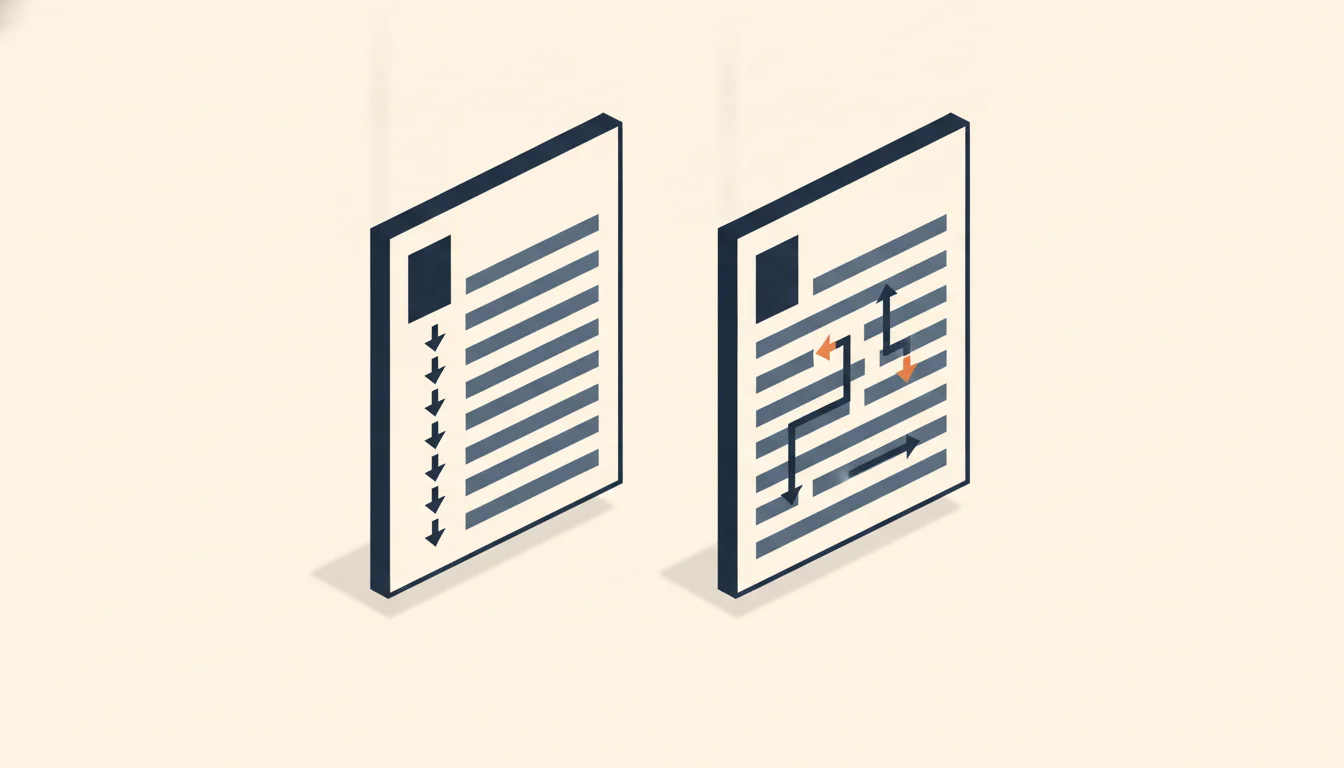
A PDF stores positioned characters, not paragraphs. The W3C's accessibility guidance makes the same point about untagged multi-column documents: a reader may go "from top to bottom, across both columns". Our two sidebar files show both failure styles.
With the sidebar on the left and written first, the way our own old template built it, pdf.js returned the sidebar as one block before the main column:
Jordan Ellis
Product Data Analyst
CONTACT
jordan.ellis@example.com
+44 20 7946 0123
Manchester, UK
SKILLS
SQL, Python, dbt, Looker
LANGUAGES
English (Native)
SUMMARY
Product data analyst with six years in subscription software, turning event
Nothing is lost there, but a parser expecting a summary after the contact block finds a skills list. When the same columns went through pdftotext, which tries to rebuild reading order from positions, the blocks collided instead. One bullet came out as "Built the churn model that flagged at-risk accounts four weeks earlier," followed by the SKILLS heading and the skill list, and only then "lifting renewals by 6%." A parser reading that has to guess which job the skills belong to.
Moving the sidebar to the right and writing the main column first gave pdf.js the experience in the right place, but pushed the contact details to the very end. It also made pdftotext alternate between columns one line at a time: name, CONTACT, job title, email, SUMMARY, phone number. Rearranging the file traded one failure for another, and an applicant can't see which extractor sits behind a careers page.
The Word version behaved more predictably. Mammoth read the table cell by cell, so the sidebar text came first but every sentence stayed whole. That still puts your skills ahead of your experience, which matters if a system reads the first dated block as your most recent job.
Letter spacing: the heading a parser reads as "E X P E R I E N C E"
Wide letter spacing (tracking) on uppercase headings looks elegant on screen. Extraction tools have to infer where words end from the gaps between characters, and wide tracking makes the gaps inside a word look like word breaks.
On 11pt headings, 0.4pt and 1pt of spacing came out as normal words in all three PDF modes. At 1.5pt and 2pt, pdf.js split all four headings into single letters, and pdftotext rejoined three of them but still returned "E D U C AT I O N". A parser that matches section names line by line finds no Education heading.
Names are less predictable, because the split depends on the exact letter pairs. We rendered six names in uppercase at 22pt in two fonts and five spacings, 60 files in all, and extracted them with pdf.js:
| Letter spacing on a 22pt name | Inter (sans-serif) intact | EB Garamond (serif) intact |
|---|---|---|
| 0 to 1pt | 6 of 6 | 6 of 6 |
| 2pt | 6 of 6 | 4 of 6 ("JANE D OE", "MARIA LIND QVIST") |
| 3pt | 0 of 6 | 0 of 6 |
The garbled names in that table are not hypothetical. "JANE D OE" is exactly what our own Classic template produced for its sample name before we lowered its letter spacing. In proportional terms, splits started between roughly 0.09 and 0.14 of the font size. Greenhouse lists "spaces between the letters" as a parse-failure cause, and this is the mechanism behind it.
Word headers, text boxes and contact icons
The single most damaging result in the test came from the most ordinary Word habit: putting your name and contact line in the page header. Mammoth's output for that file began at "Summary". The name, email and phone were absent. Mammoth's documentation lists the parts of a .docx it converts (headings, tables, text boxes, footnotes and more), and page headers aren't on the list. Greenhouse names the same placement as a failure cause. If a system reads your file this way, the recruiter gets a profile with no name and no way to call you.
A text box was less harmful than its reputation. Mammoth documents that a text box's content is treated as a separate paragraph after the paragraph that contains it, and in our file the name and contact details came out first and intact. Greenhouse still lists text boxes as a risk, so the safe placement remains the plain body.
In the PDFs, a box positioned at the top of the page but written last into the file reversed the result: pdf.js returned the name and email at the very end, after the skills, while pdftotext put them back on top.
Icon fonts were the mildest problem. A Font Awesome envelope, phone and pin each came out as an unreadable private-use character in front of the details, in all three modes. The email and phone number themselves survived. A parser that expects "Email:" or nothing before an address may still stumble, and a label costs you nothing.
What this test can't tell you
Our tools are not any vendor's parser. Workday, Greenhouse and the parsing companies behind many ATS run their own, usually proprietary, code and may detect columns far better than pdf.js does. What the test shows is the raw material: the text and order a parser starts from. When that raw material differs between three free tools, the outcome inside an unknown commercial system is a gamble.
The limits matter:
- One fictional resume, generated by code. Files exported from Canva, Word or InDesign may encode text differently.
- No real ATS was tested; we had no access to employer accounts.
- Tagged PDFs, which carry an explicit reading order for accessibility, were not part of this run.
We applied the findings to our own product before publishing. Our Professional template used a dark two-column sidebar until this test; it is now a single column with a header band, and every template caps heading letter spacing at 0.4pt. If you want to see how your own file extracts, you can run your resume through our free ATS check, which shows the raw text a parser pulled from your upload, or export the PDF to plain text and read it top to bottom. For what happens after parsing, when a ranking system scores the record, see how AI resume screening works.
Is a two-column resume bad for ATS?+
It is a risk you can't measure in advance. In our test every two-column layout was reordered or had sentences cut by at least one of three common extraction tools, while the single column came out clean in all of them. Greenhouse lists columned layouts as a parse-failure cause; Textkernel says its parser detects columns. A single column avoids the question.
Can ATS read a 2 column resume made in Word?+
If the columns are built with a table, the text usually survives but is read cell by cell, so the sidebar can come before your experience. If your name and contact details sit in the Word page header, some extractors drop them entirely, as mammoth did in our test.
Is letter spacing on resume headings safe?+
Small amounts are. On 11pt headings, 1pt of letter spacing extracted normally in our test, while 1.5pt and more turned headings into single letters in pdf.js. Keep tracking well under a tenth of the font size, or leave it off.
Are icons in the contact section a problem?+
Less than often claimed. Icon-font glyphs came out as unreadable characters but did not hide the email or phone. Writing the label in plain text, or dropping the icon, removes the stray character.
Key takeaways
- A two-column resume is a bet on the employer's parser: Textkernel advertises column detection, while Greenhouse lists columned layouts among the causes of failed parses.
- In our 15-layout test, the single column was the only arrangement that extracted identically in pdf.js, pdftotext and mammoth; each two-column variant failed in at least one of them.
- Columns fail in two ways: the sidebar is read as a separate block before or after your experience, or a layout-guessing extractor cuts sentences in half and interleaves the columns.
- Letter spacing above about a tenth of the font size turns headings and names into separate letters, which is what "spaces between the letters" means in Greenhouse's failure list.
- Keep your name and contact details out of the Word page header: the extractor we tested dropped them completely, which leaves a recruiter with an anonymous profile.